Research
Introducing Phonon-2
The most accurate open speech recognition model under 900 MB, in a 164 MB download that turns an hour of audio into text in about 20 seconds on a MacBook Air.
 Speech recognition · Available now
The most accurate open speech recognition model under 900 MB. 164 MB, 5.21 % word error on seven public test sets, 174× realtime on a MacBook Air.
Overview
Phonon-2 is the most accurate open speech recognition model under 900 MB. In a 164 MB download it averages 5.21 % word error on the Open ASR Leaderboard’s seven English sets, and every open model that scores better is at least 5.8 times its size. Set for set it holds the accuracy of its 2.5 GB full-precision teacher and beats it on meetings and parliamentary speech. Its encoder stores every weight as one of five learned levels in about 2.1 bits.
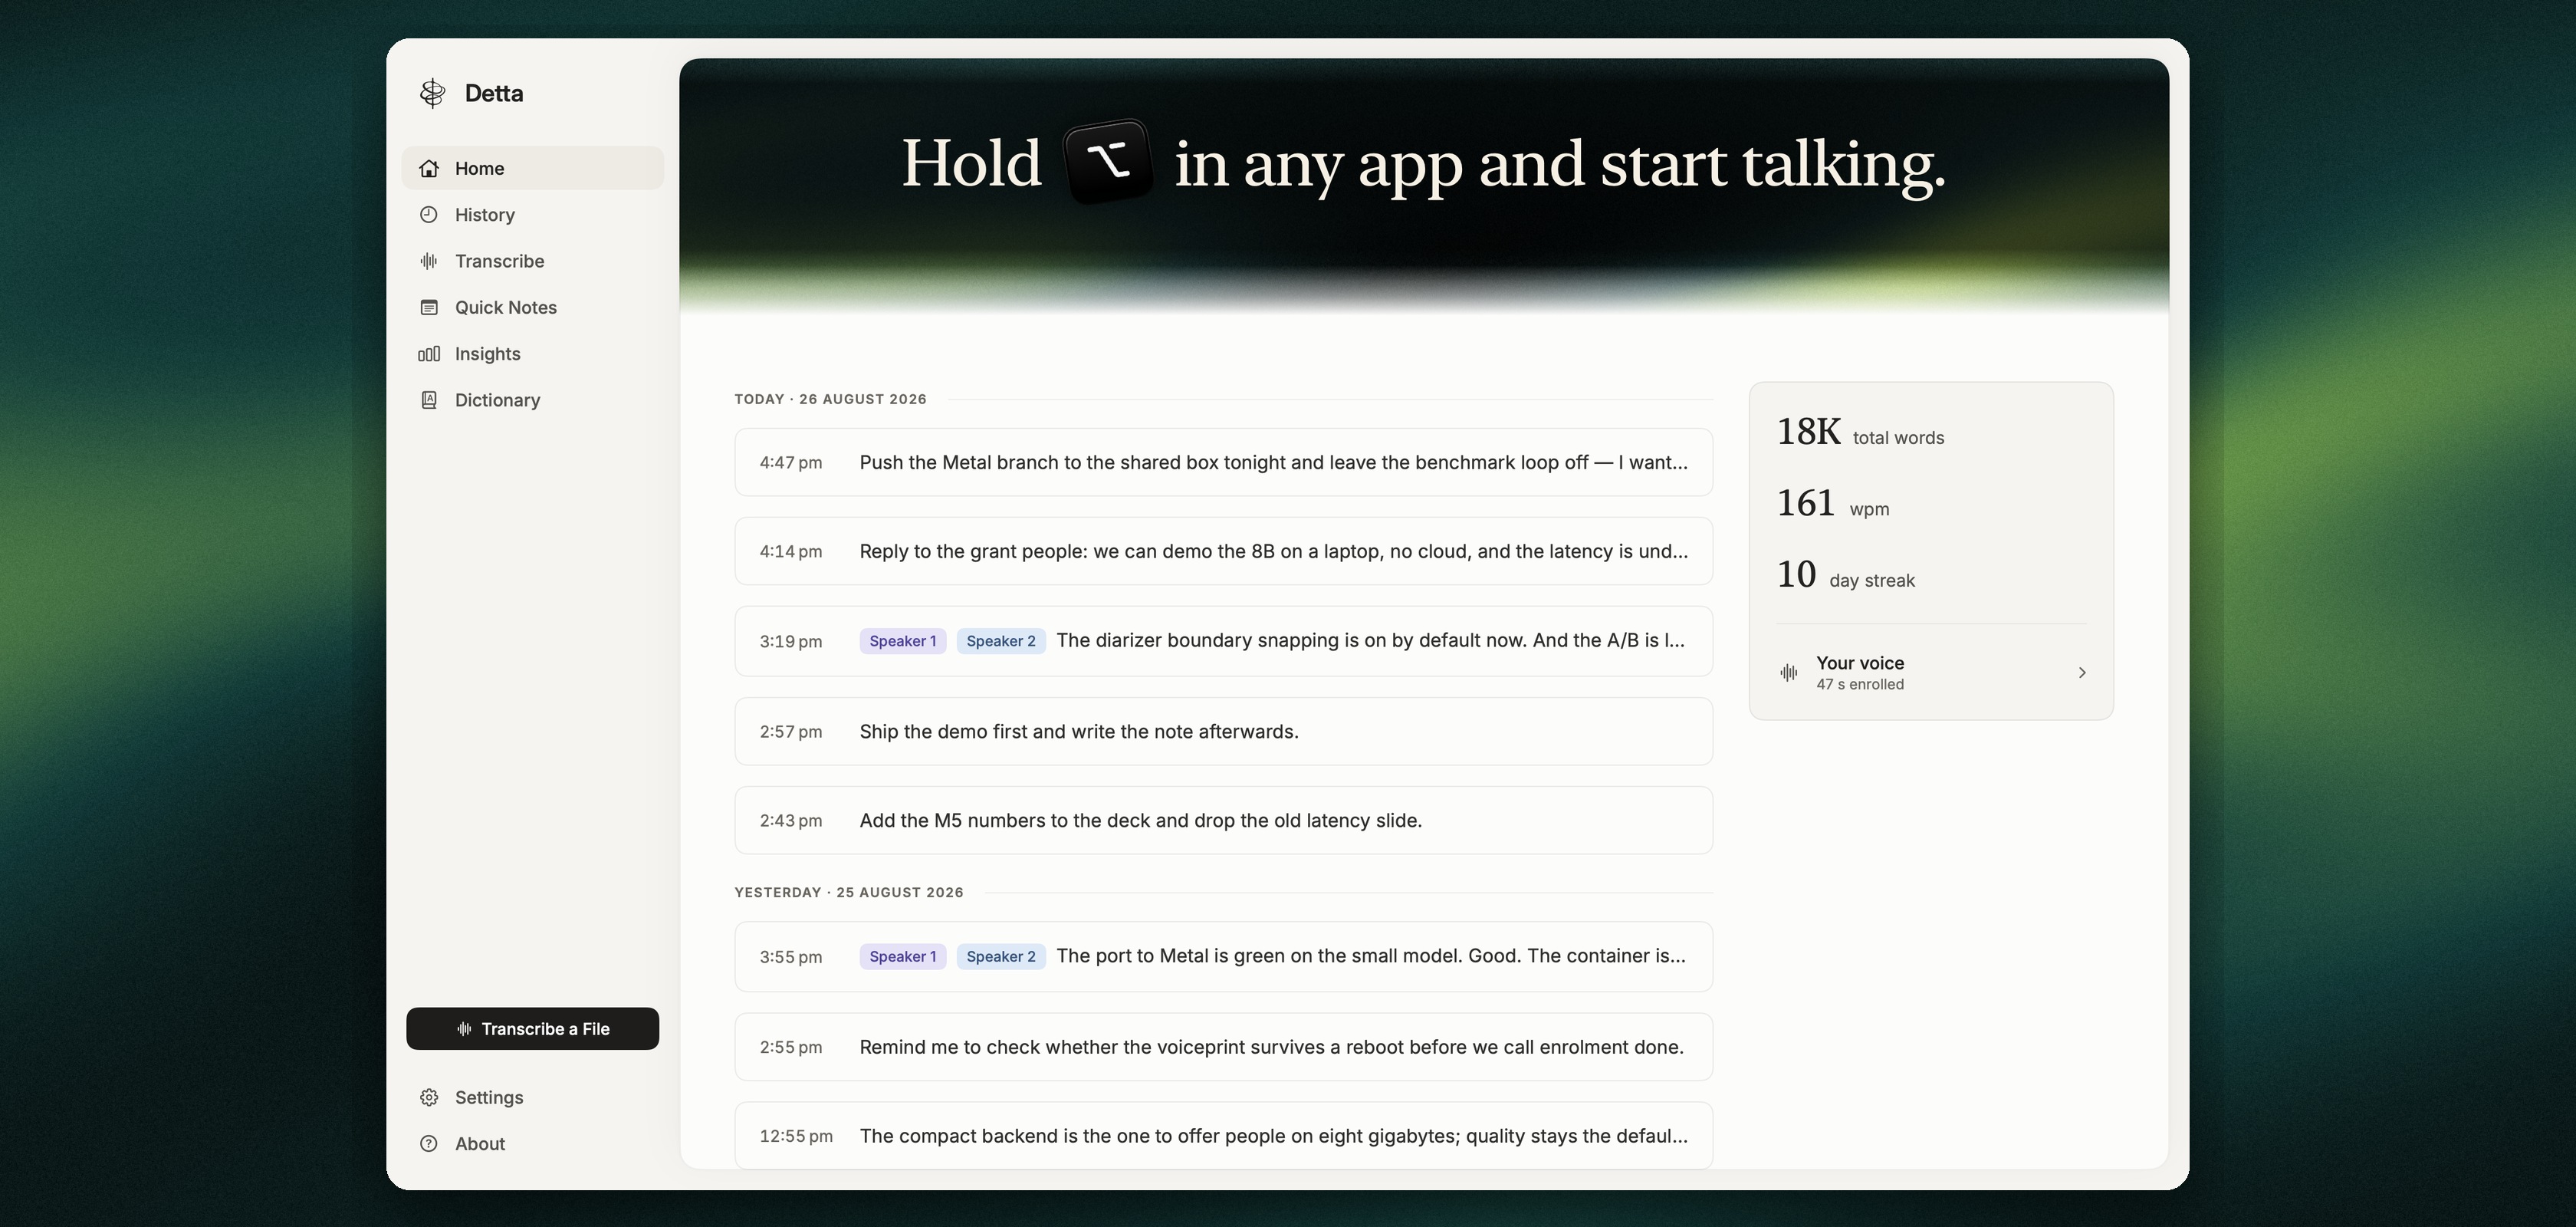
It transcribes at 174 times realtime on an M5 MacBook Air, where Parakeet TDT 0.6B v3 in FluidAudio’s Core ML runtime reaches 104.9 on the same audio; at 143 times on eight Zen 5 cores (16 vCPU); and at 6,680 times on one H100 in batches of 128. A Core ML runtime for Apple devices is coming soon. The model writes punctuated, capitalized text, and the weights are released under CC-BY-4.0. Phonon-2 is the model behind Detta, the Fermion Research dictation app for the Mac.
Models
Phonon-2 is a single file. Phonon-1 remains available beside it.
Evaluation
Phonon-2 averages 5.21 % word error on the seven public test sets of the Open ASR Leaderboard, scored with the board’s own code on the full test sets. The table sets it beside its full-precision teacher, Parakeet TDT 0.6B v3, which averages 4.96 in a 2,508 MB download, and six other open models from 178 MB to about 8 GB.
Seven-set comparison
| Model | Params | Download | LS clean | LS other | AMI | Earnings-22 | GigaSpeech | SPGISpeech | VoxPopuli | Average |
|---|---|---|---|---|---|---|---|---|---|---|
| Phonon-2Fermion Research | 0.60 B | 164 MB | 1.72 | 3.92 | 9.37 | 6.96 | 8.35 | 3.70 | 2.46 | 5.21 |
| parakeet-tdt-0.6b-v3nvidia | 0.60 B | 2,508 MB | 1.52 | 3.13 | 9.42 | 5.85 | 7.99 | 3.63 | 3.19 | 4.96 |
| Parakeet ReduxMoondream | 0.60 B | 178 MB | 1.94 | 4.35 | 9.16 | 7.90 | 8.62 | 4.01 | 3.87 | 5.69 |
| Phonon-1Fermion Research | 0.78 B | 415 MB | 2.11 | 5.03 | 10.31 | 12.34 | 8.73 | 3.67 | 3.73 | 6.56 |
| canary-180m-flashnvidia | 0.18 B | 737 MB | 1.52 | 3.42 | 12.09 | 8.33 | 8.87 | 2.04 | 3.57 | 5.69 |
| Voxtral-Mini-4B-Realtime-2602mistralai | 4.00 B | 8,000 MB* | 1.62 | 4.94 | 13.34 | 9.31 | 8.80 | 2.23 | 2.60 | 6.12 |
| whisper-large-v3-turboopenai | 0.80 B | 1,618 MB | 2.13 | 3.71 | 13.88 | 8.09 | 8.47 | 2.79 | 7.02 | 6.58 |
| nemotron-3.5-asr-streaming-0.6bnvidia | 0.64 B | 2,368 MB | 2.83 | 6.79 | 13.43 | 15.30 | 9.86 | 3.27 | 4.24 | 7.96 |
Phonon-2Fermion Research · 0.60 B · 164 MB
parakeet-tdt-0.6b-v3nvidia · 0.60 B · 2,508 MB
Parakeet ReduxMoondream · 0.60 B · 178 MB
Phonon-1Fermion Research · 0.78 B · 415 MB
canary-180m-flashnvidia · 0.18 B · 737 MB
Voxtral-Mini-4B-Realtime-2602mistralai · 4.00 B · 8,000 MB*
whisper-large-v3-turboopenai · 0.80 B · 1,618 MB
nemotron-3.5-asr-streaming-0.6bnvidia · 0.64 B · 2,368 MB
Throughput
One 164 MB file runs on every surface, and the fast path on each keeps the accuracy of the exact one.
| Surface | Times realtime | Word error, fast path against exact path |
|---|---|---|
| Apple M5 MacBook Air, GPU (MLX) | 174× | 2.94 % against 2.94 % (400 LibriSpeech utterances) |
| Apple M5 MacBook Air, CPU only | 40× | 2.33 % on a 40-clip check |
| Linux x86-64, eight Zen 5 cores (16 vCPU) | 142.8× | 3.94 % against 3.91 % (LibriSpeech test-other) |
| Linux Arm, eight Google Axion cores | 52.2× | 3.90 % against 3.91 % (LibriSpeech test-other) |
| Windows x64, 8 vCPU | 21.0× | 2.21 % on a 40-clip check |
| NVIDIA A100 80 GB | 267× one stream · 3,614× batch 128 | 5.20–5.22 % against 5.20 % (seven sets) |
| NVIDIA H100 80 GB | 465× one stream · 6,680× batch 128 | 5.20–5.22 % against 5.20 % (seven sets) |
| Runtime on the same M5 MacBook Air | Times realtime |
|---|---|
| Phonon-2 (MLX) | 174.0× |
| FluidAudio, Parakeet TDT 0.6B v3 (Core ML) | 104.9× |
| FluidAudio, Parakeet Redux (Core ML) | 27.8× |
| Moonshine tiny | 26.7× |
| whisper.cpp, large-v3-turbo (Metal) | 17.0× |
| sherpa-onnx, Parakeet TDT 0.6B v3 (int8) | 16.5× |
Run it
Phonon-2 is the model inside Detta, the dictation app for the Mac.
$ pip install fermion-research$ pip install mlx mlx-audio mlx-lm soundfile scipy zstandard$ fermion transcribe recording.wav --model phonon-2
On a Mac with Apple silicon, the second line installs the speech runtime and the model downloads on first use. The name phonon on its own also selects Phonon-2, and --model phonon-1 selects the earlier model.
$ fermion listen --model phonon-2$ fermion serve --model phonon-2
fermion listen transcribes the microphone live, and fermion serve runs a local OpenAI-compatible transcription endpoint.
$ docker run --rm -v "$PWD":/audio ghcr.io/fermionresearch/phonon-cpu:2.0.2 transcribe /audio/recording.wav --model phonon-2$ docker run --rm --gpus all -v "$PWD":/audio ghcr.io/fermionresearch/phonon-cuda:1.0.3 transcribe /audio/recording.wav --model phonon-2
The same package runs on Linux (x86-64 and Arm) and Windows CPUs. With Docker, Phonon-2 runs on a CPU or a GPU.
Weights on Hugging Facefermion-research on PyPIEngines on GitHub
Availability
The weights are released under the Creative Commons Attribution 4.0 licence, which Phonon-2 inherits from NVIDIA’s Parakeet TDT 0.6B v3. The licence permits commercial use, modification and redistribution with attribution. The command line is released under Apache 2.0.
@misc{fermionresearch2026phonon2,
  title  = {Phonon-2},
  author = {{Fermion Research}},
  year   = {2026},
  url    = {https://fermionresearch.com/models/phonon-2/}
}